
CloudHub 2.0 High Availability and Disaster Recovery
CloudHub 2.0 provides high availability (HA) and disaster recovery (DR) for applications and protects against hardware failures.
For an overview of HA and DR across all Mule deployment models, and to compare CloudHub 2.0 with other options, see High Availability and Disaster Recovery Across Deployment Models.
CloudHub 2.0 runs on Amazon AWS, so its availability depends on Amazon services. CloudHub 2.0 bases deployments and availability on regions that correspond to Amazon regions. If an Amazon region goes down, applications in that region become unavailable, and CloudHub 2.0 doesn’t automatically replicate them to other regions.
During a network partition between the control plane and the runtime plane, applications in the runtime plane keep running. The runtime plane buffers log and telemetry data locally until control plane availability returns.
High Availability Versus Disaster Recovery
High availability (HA) measures a system’s ability to remain accessible when a component fails. You implement HA by building multiple levels of fault tolerance and load balancing into a system. On CloudHub 2.0, you achieve HA by deploying your application with multiple replicas.
Disaster recovery (DR) restores a system to an acceptable previous state after a natural or man-made disaster, such as flooding, tornadoes, earthquakes, fires, power failures, server failures, or misconfigurations.
Both strategies increase availability but differ in scope: on CloudHub 2.0, HA keeps your application serving requests through replica and availability-zone failures with no loss of service, whereas DR restores service and data after a region-level disruption and usually incurs a brief loss of service while the DR plan runs.
Two measurable objectives drive your HA and DR strategies on CloudHub 2.0:
- Recovery Time Objective (RTO)
-
The maximum downtime a business tolerates. RTO is the time the system takes to recover after a disruption.
- Recovery Point Objective (RPO)
-
The maximum data loss a business accepts after a disaster. RPO drives how often you back up data.
High Availability in CloudHub 2.0
CloudHub 2.0 builds high availability into the platform through mechanisms that MuleSoft manages automatically and that require no additional configuration.
- Multiple-replica deployment
-
When an application uses multiple replicas, CloudHub 2.0 deploys those replicas across two or more availability zones (AZs) by default. If an AZ fails, CloudHub 2.0 automatically restarts the application in a different AZ to maintain availability.
CloudHub 2.0 Improvements Over CloudHub
CloudHub 2.0 improves on CloudHub in these areas:
-
Decouples the runtime plane region from the control plane region through a service-oriented architecture.
-
Supports clustering, which lets you configure HA while running the process on a single primary replica.
-
Optimizes usage through elastic scaling with Horizontal Pod Autoscaling (HPA) for scaled-down hot standby deployments when not in use and then scaling up when a failover is required.
-
Manages applications in active/passive mode, which lets you set schedulers and listening connectors—such as Anypoint MQ, Database, FTP, and Salesforce listeners—to a stopped or inactive state. Externalize DR flags and expose REST endpoints to enable and disable flows through a Groovy script as needed.
Disaster Recovery in CloudHub 2.0
Disaster recovery in CloudHub 2.0 focuses on restoring systems after significant disruptions. MuleSoft manages in-region infrastructure, and you own your cross-region DR strategy.
Global Distribution
You can deploy applications to CloudHub 2.0 in global regions across North America, South America, the European Union, and Asia-Pacific.
With the Global Deployment entitlement, and in the US Cloud or EU Cloud, you can deploy applications to more than one runtime plane region.
To reduce latency, host integrations in a runtime plane region closer to your services.
For the runtime plane regions available for your control plane region, see Runtime Plane Regions and DNS Records. The runtime plane region is where you deploy your CloudHub 2.0 applications and create CloudHub 2.0 private spaces.
Your Responsibility for Disaster Recovery
If your organization has cross-region DR requirements, build your applications accordingly and consider deploying them across multiple regions. For applications deployed to different regions, use a cloud-based or on-premises load balancer to switch traffic to your backup region as part of your DR strategy.
For more about how to deploy for HA and DR strategies, see High Availability and Disaster Recovery Across Deployment Models.
Disaster Recovery Use Cases for the Runtime Plane
CloudHub 2.0 supports multiple multiregion DR strategies based on application impact. These strategies typically use a bring-your-own (BYO) global load balancer to manage traffic distribution and failover across regions.
To decouple your runtime plane application availability from the control plane region, configure your primary and backup runtime plane regions to differ from the region that hosts your Anypoint Platform control plane. This guidance applies to the EU, with the control plane in eu-central-1, and to the US, with the control plane in us-east-1.
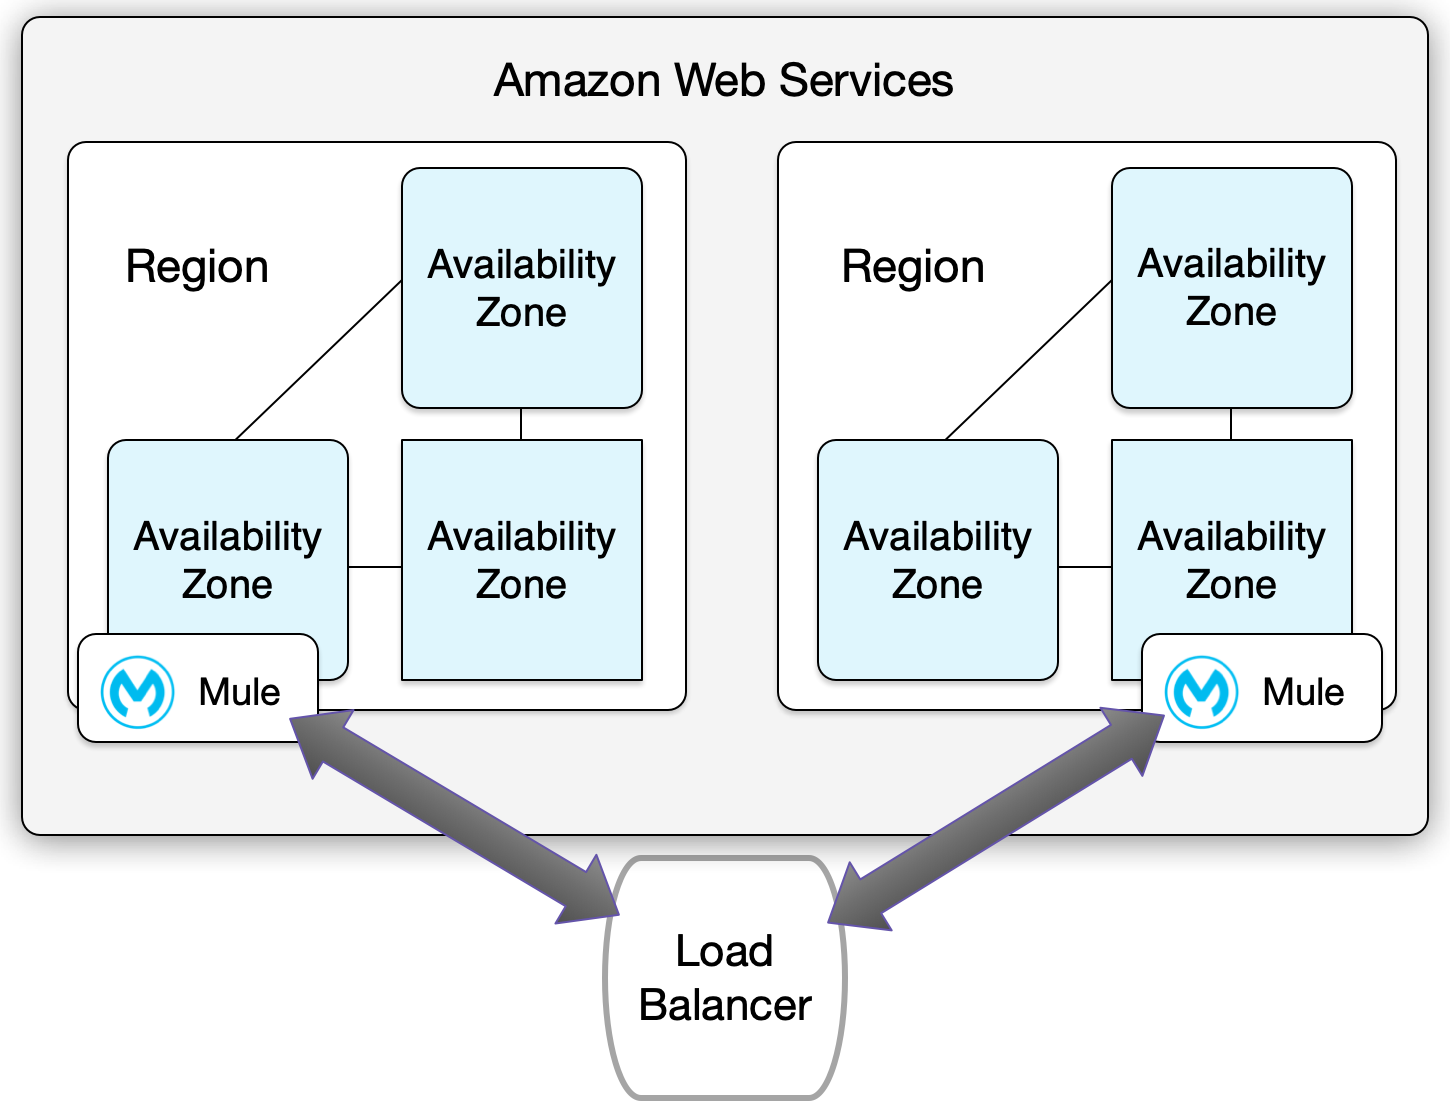
Active-Active Configuration
When to use: Choose this configuration for high-impact applications that require continuous availability with minimal downtime.
Application state: Run applications in different regions simultaneously and fully scaled up.
Traffic management:
-
Distribute traffic between both regions with a BYO global load balancer.
-
Run health checks to detect disasters.
-
Keep applications running even when the control plane region is unavailable, as long as you deploy them in different regions than the control plane.
Licensing:
-
With usage-based pricing (UBP), this configuration distributes Mule messages and data throughput between the two regions and consumes Mule flows based on the number of running replicas per application deployment.
-
Without UBP, this configuration consumes additional vCores.
Hot Standby (Active-Passive) Configuration
In a hot standby configuration, you install, configure, and fully run your backup environment in the passive region, but it doesn’t process requests until you detect an outage.
When to use: Choose this configuration for high-impact APIs that can only tolerate brief downtime during failover.
Application state:
-
Set up infrastructure across multiple regions, and deploy and run your backup applications in the passive region.
-
Run the backup applications either fully scaled up or scaled down, with fewer replicas or smaller replica sizes. Scaled-down applications rely on the control plane to redeploy, start, or scale up during an outage.
-
For scaled-down backup applications, configure CPU-based Horizontal Pod Autoscaling (HPA) where your organization supports it. See Configuring Horizontal Autoscaling (HPA) for CloudHub 2.0 Deployments.
Traffic management:
-
Route traffic to only one region at a time with a BYO global load balancer or DNS routing, such as Amazon Route 53.
-
Run health checks to determine DR and switch routing.
-
For non-HTTP use cases such as schedulers, externalize a DR flag in your application and use a Groovy script to enable and disable scheduler flows directly in the runtime plane. Because the backup application is already running, this approach doesn’t rely on the control plane to activate your backup applications.
Licensing:
-
With UBP, this configuration consumes no messages or throughput until traffic switches to the backup region, and it consumes fewer flows when you configure CPU-based HPA.
-
Without UBP, this configuration consumes additional vCores for the backup deployment. It consumes fewer vCores when the backup deployment stays scaled down before it scales up in response to an outage in the primary region.
Recovery time objective: A fully scaled backup application has minimal to no downtime, covering only the time to route traffic to the backup region. A scaled-down backup application has an RTO that depends on the time to scale up, either through control-plane-triggered redeployments or through CPU-based HPA. To let integrating systems resend events or in-flight transaction data, capture recovery points in logs and monitoring systems to improve application reliability.
Warm Standby Configuration
In a warm standby configuration, you fully set up your backup infrastructure in the passive region and deploy your backup applications, but no applications run until you detect an outage.
When to use: Choose this configuration for medium-impact APIs that can only tolerate brief downtime during failover.
Application state:
-
Create and configure your private space, including networking, in the passive region. A running private space is equivalent to a running production system or virtual machine in an on-premises environment.
-
Configure API Manager for your backup APIs in the passive region.
-
Deploy your backup applications to the passive region in a stopped state, for example, by setting
<autoStart>false</autoStart>in your deployment configuration. -
Start the applications only when you detect an outage.
Traffic management:
-
Route traffic only to the region that is up with a BYO global load balancer or DNS routing, such as Amazon Route 53.
-
Run health checks to determine DR, and use scripts to start your backup applications and switch traffic routing.
-
If the control plane is unavailable, you cannot start the backup application in the runtime plane.
Licensing: The private space and API Manager configuration in the passive region consume your entitlements for the DR region. Because the backup applications stay stopped, this configuration consumes no additional vCores, Mule flows, Mule messages, or data throughput until the backup applications start during a disaster.
Recovery time objective: Your RTO depends on the time to start applications through the control plane and route traffic to the backup region.
Cold Standby Configuration
In a cold standby configuration, nothing runs in the passive region, and you keep your expense to a minimum. Your cold standby is a plan or script that builds your backup environment in the passive region after you detect an outage.
When to use: Choose this configuration for low-impact applications that tolerate longer downtime during recovery.
Application state:
-
Don’t create a private space or deploy applications or gateways in the passive region before an outage.
-
Maintain a plan or script that, when you detect an outage:
-
Creates a private space and other infrastructure connectivity, such as VPNs and transit gateway attachments, in the passive region.
-
Deploys and starts your Mule applications and Omni Gateway instances.
-
Deploys your API policies.
-
-
Keep the artifacts and configuration that your plan or script uses available outside the primary region, for example, in Exchange and in your source control or CI/CD pipeline.
Traffic management:
-
Run health checks to determine DR, run your plan or script to build the backup environment, and switch traffic routing.
-
If the control plane is unavailable, you cannot create the private space or deploy the backup applications.
Licensing: Because nothing runs in the passive region, this configuration consumes no private space, vCore, Mule flow, Mule message, or data throughput entitlements for the DR region until you build the backup environment during a disaster.
Recovery time objective: Your RTO depends on the time your plan or script takes to create the private space and infrastructure connectivity, deploy and start your Mule applications and Omni Gateway instances, and deploy your API policies, plus the time to route traffic to the backup region. This configuration has the longest RTO of the standby options.
Runtime Plane High Availability and Disaster Recovery Summary
- High-impact API
-
Use an active-active setup with active replicas in two regions and an external load balancer.
- High-impact API
-
Use a hot standby setup with fully scaled backup applications running in the secondary region. Use an external load balancer to route traffic, and run health checks to determine DR and switch traffic.
- Medium-impact API
-
Use a hot standby setup with scaled-down backup applications, or a warm standby setup with backup applications deployed but stopped in the secondary region.
- Low-impact API
-
Use a cold standby setup, and create the private space and deploy your backup applications in the secondary region only when you detect an outage.
Disaster Recovery for Regional Services
Some MuleSoft services are regional, which shapes their DR strategy.
- Anypoint MQ
-
This regional service runs in the same region as the application and provides out-of-the-box region failover to a fallback region for standard queues. When your application’s RTO tolerates processing in-flight messages only after the primary site recovers, Anypoint MQ failover suffices. Otherwise, configure a backup application in an active/passive setup and resend in-flight events and data to the failover queue during a traffic switch. During backup with VM queues and Anypoint MQ, you can lose data for a few minutes, depending on your configuration.
- Object Store v2
-
This regional service runs in the same region as the application and provides no region failover. An application deployed in a different region cannot access it. Bring your own external storage to access or back up data across regions. Object Store v2 doesn’t retrieve data for regular backups. Caching in the object store, which you use for token management between calls, is region-specific, and you cannot transfer it to a secondary region.
Disaster Recovery for the Anypoint Platform Control Plane
The Anypoint control plane covers additional Anypoint services beyond CloudHub 2.0. For details, see the DR Test Summary.
Considerations and Limitations
Considerations for Disaster Recovery Implementations
A DR strategy for applications deployed to CloudHub 2.0 requires you to consider several factors.
- Control plane availability
-
The CloudHub 2.0 management UI and control plane run in the US East region of North America, and also in the EU, Canada, and Japan. See Control Plane and Runtime Plane Support Matrix.
- Caching
-
Use caching in the object store to share tokens among calls. Object stores are region-specific, and you cannot transfer them to a secondary region.
- Rate-limiting API policies
-
Rate-limiting policies apply at the replica level. When you need rate limiting for in-flight transactions during DR, define custom policies that use an external multiregion shared object store, and include a DR playbook with steps to adjust rate limits during and after DR.
- Schedulers
-
Many applications run on a schedule to read from databases or files. In this case, schedulers keep running even when the control plane is briefly unavailable.
- Listeners and watermarks
-
For listeners such as Database Table Row and Salesforce Events, use an external persistent store, such as a database or Redis, across replicas and regions for polling and watermarks. This matters only when connectors use watermarks directly or indirectly.
Best Practices
-
Keep your integrations stateless.
-
Don’t share transactional information between client invocations or scheduled executions.
-
If the middleware must retain data because of a system limitation, persist it in an external store, such as a database or a messaging queue, rather than in the middleware infrastructure or memory.
-
Keep each replica’s state and resources independent so that your applications scale and recover reliably across zones and regions.